Posts

Heaps

The (binary) heap data structure is an array object that we can view as a nearly complete binary tree. Heapsort uses heap data structure to manage its information. In this article, we present one of the most popular applications of a heap: as an efficient priority queue. [1] Usually, a priority queue has a contract with methods to insert an element into it, examine the head of the queue, and to remove the element at the head of the queue. Here’s our contract for the priority queue. Next, we have to implement this contract. Here’s how it looks. Now, we have the priority queue under our belt, we can go ahead and use it to solve real world problems. Even though it is much easier to come up with a slightly contrived example of using the priority queue, this time around, I thought of coming up with a more real example which showcases the real capabilities of our data structure. The beauty of this approach is that it pounds on the data structure so much and allows us to find any vulne...

Binary Search Tree - Iterative inorder tree walk

Image
Today, I’ll walk you through an iterative algorithm for inorder tree walk over a Binary search tree. First, let me draw your attention to an exercise in the CLRS book [1]. Exercise 12.1-3 Give a nonrecursive algorithm that performs an inorder tree walk. (Hint: An easy solution uses a stack as an auxiliary data structure. A more complicated, but elegant, solution uses no stack but assumes that we can test two pointers for equality.) The one which uses a stack is relatively simple. Here’s how it looks. **Input:** $root$ node of the tree $T$   $INORDER-TREEWALK-ITERATIVE(root)$   $\phantom{{}++{}}$ Let $s$ be an empty stack   $\phantom{{}++{}}$ TreeNode $\;\;current \gets root$   $\phantom{{}++{}}$  `while`$\;!s.isEmpty$ or $current \;\neq sentinel$   $\phantom{{}++{}}$  $\phantom{{}++{}}$ `if` $current \neq sentinel$   $\phantom{{}++{}}$  $\phantom{{}++{}}$ $\phantom{{}++{}}$  $s.push(current)$   $\phantom{{}++{}}$  $\phantom{{}+...

Merge Sort

The divide-and-conquer paradigm involves three steps at each level of the recursion: Divide the problem into a number of subproblems that are smaller instances of the same problem. Conquer the subproblems by solving them recursively. If the subproblem sizes are small enough, however, just solve the subproblems in a straightforward manner. Combine the solutions to the subproblems into the solution for the original problem. The merge sort algorithm closely follows the divide-and-conquer paradigm. [1] The key operation of the merge sort algorithm is the merging of two sorted sequences in the “combine” step. We merge by calling an auxiliary procedure MERGE(A, p, q, r), where A is an array and p, q, and r are indices into the array such that $p ≤ q < r$. The procedure assumes that the subarrays A[p..q] and A[q+1..r] are in sorted order. It merges them to form a single sorted subarray that replaces the current subarray A[p..r]. Our MERGE procedure takes time $Θ(n)$, where $n = r - p + ...

Edit distance

Image
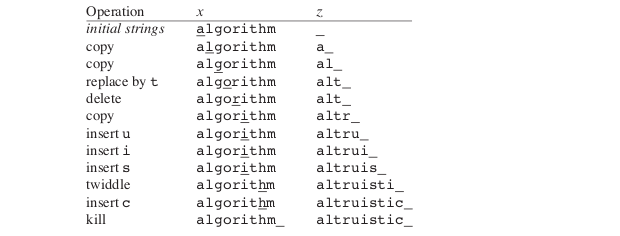
Biological applications often need to compare the DNA of two (or more) different organisms. A strand of DNA consists of a string of molecules called bases, where the possible bases are adenine, guanine, cytosine, and thymine. Representing each of these bases by its initial letter, we can express a strand of DNA as a string over the finite set $\{A, C, G, T\}$. For example, the DNA of one organism may be $S1 = ACCGGTCGAGTGCGCGGAAGCCGGCCGAA$, and the DNA of another organism may be $S2 = GTCGTTCGGAATGCCGTTGCTCTGTAAA$. One reason to compare two strands of DNA is to determine how “similar” the two strands are, as some measure of how closely related the two organisms are. We can, and do, define similarity in many different ways. For example, we can say that two strands are similar if the number of changes needed to turn one into the other is small. [1] We formalize this notion of similarity in our Edit distance problem. 15-5 Edit distance - Problem Statement In order to transform one sour...

Red-Black Trees

Image
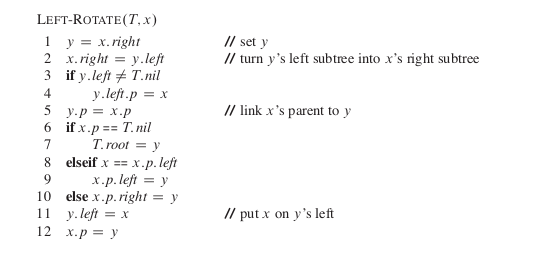
Red-black trees are one of many search-tree schemes that are balanced in order to guarantee that basic dynamic-set operations take $Θ(log_2 \;n)$ time in the worst case. [1] A red-black tree is a binary search tree with one extra bit of storage per node: its color, which can be either RED or BLACK. Every red-black tree should satisfy the following red-black properties: [1] Every node is either red or black. The root is black. Every leaf ( NIL ) is black. If a node is red, then both its children are black. For each node, all simple paths from the node to descendant leaves contain the same number of black nodes. As a matter of convenience in dealing with boundary conditions in red-black tree code, we use a single sentinel to represent NIL. Its color attribute is BLACK , and its other attributes - p, left, right, and key—can take on arbitrary values. Although we instead could add a distinct sentinel node for each NIL in the tree, so that the parent of each NIL is well defined, t...

Longest Palindromic Substring

A palindrome is a nonempty string over some alphabet that reads the same forward and backward. Examples of palindromes are all strings of length 1, civic, racecar, and aibohphobia (fear of palindromes). Given a string $s$, find the longest palindromic substring in $s$. You may assume that the maximum length of $s$ is $1000$. Example 1: Input: "babad" Output: "bab" Note: "aba" is also a valid answer. Example 2: Input: "cbbd" Output: "bb" Let $p[i][j]$ be a table that states whether the substring $s_i\ldots s_j$ is a palindrome or not. Note that any substring of $length = 1$ can be considered as a palindrome. The following equation describes  the recurrence. $p[i][j] = \begin{cases} true ,  & \text{if $l = 1$} \\[2ex] s_i == s_j,   & \text{if $l = 2$} \\[2ex] p[i+1][j-1]\; and \; s_i == s_j, & \text{if $len \gt 2$} \end{cases}$ Procedure LONGEST-PALINDROME-SUBSTRING takes a String as it’s input. It stores $p[...

Optimal binary search trees

Image
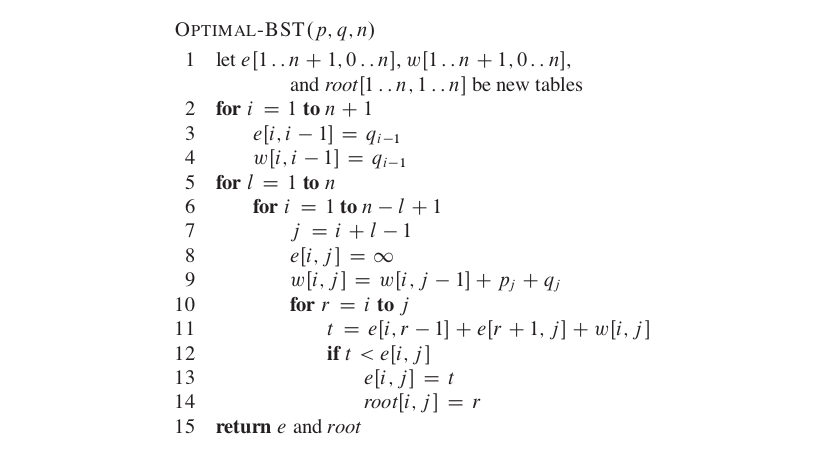
Suppose that we are designing a program to translate text from English to French. For each occurrence of each English word in the text, we need to look up its French equivalent. We could perform these lookup operations by building a binary search tree with $n$ English words as keys and their French equivalents as satellite data. Because we will search the tree for each individual word in the text, we want the total time spent searching to be as low as possible. We could ensure an $Θ(log_2 \;n)$ search time per occurrence by using a red-black tree or any other balanced binary search tree. Words appear with different frequencies, however, and a frequently used word such as the may appear far from the root while a rarely used word appears near the root. Such an organization would slow down the translation, since the number of nodes visited when searching for a key in a binary search tree equals one plus the depth of the node containing the key. We want words that occur frequently in the t...